Autoraters 101
A short course on evaluating generative AI with LLMs as judges — so you can stop guessing whether a model is good and start measuring it. Three videos, a hands-on demo, and the Python templates to run it yourself.

Why human review stops working the moment you ship a generative feature — and what replaces it.
The three reasons an LLM can judge another model's work honestly: evaluation is easier than generation, the judge can be far bigger, and it sees everything after the fact.
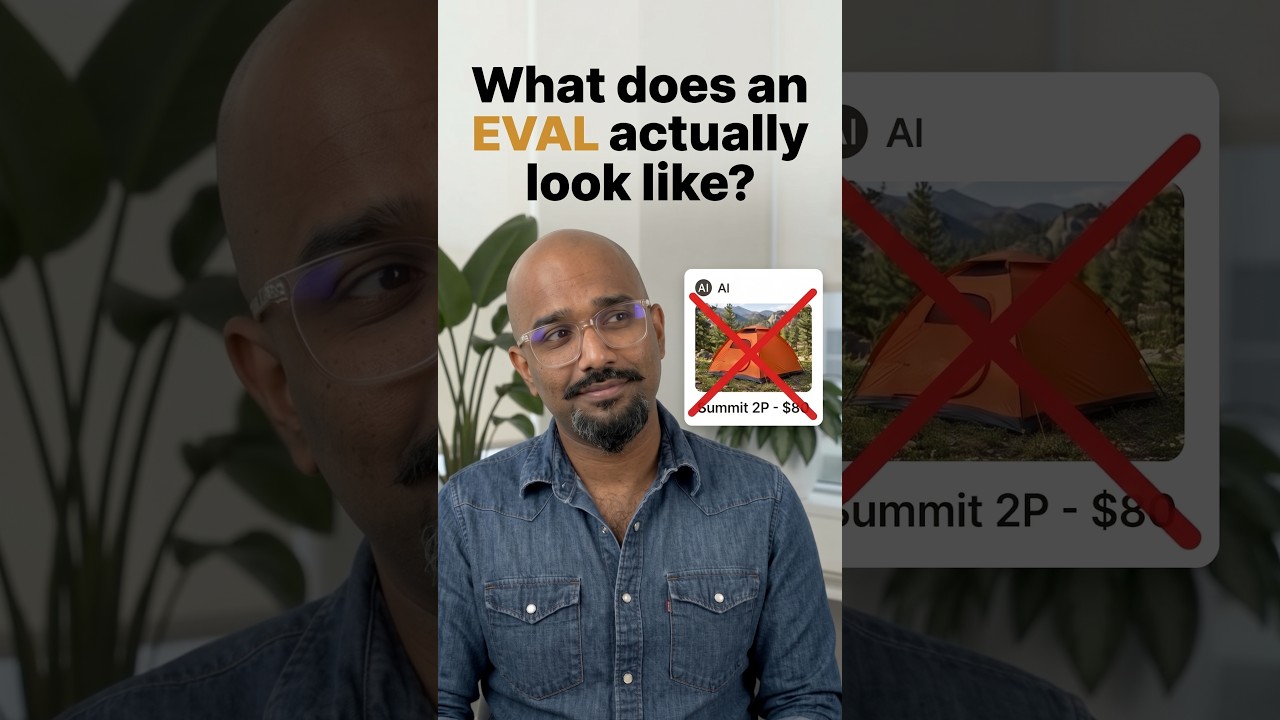
From a gut reaction to a written rubric to Python you can run over a whole test set. Score a few answers yourself, then take the code.
Course 4 is coming
Running the judge over a real test set, catching drift, and reporting agreement you can defend in a review. Get it in your inbox when it lands.
Subscribe — it's free